Privacy-First AI Learning in Your Own Homelab

Kevin Howell

2026-10-24

About Me

Principal Software Engineer at Red Hat

Raleigh, NC

@kahowell@mastodon.social

https://kahowell.net

Note

These are my own opinions and experiences; I’m not speaking for my employer.

Why Open-Source/Open-Weight

  • Ethics/morals
  • Transparency/learning
    • Log Probs
    • Structured Output
  • Sovereignty
  • Privacy

Hugging Face Incident

When we started the log analysis, we first used frontier models behind commercial APIs. This did not work.

These requests were blocked by the providers’ safety guardrails.

We ran the forensic analysis instead on zai-org/GLM-5.2, an open-weight model, on our own infrastructure.

Hugging Face - Security Incident July 2026

Note

OpenAI later admitted to compromising Hugging Face.

Poll

  • How many use AI through a subscription today?
  • How many have used AI through APIs?

What is AI, Anyway?

llms cv audio llms_label LLMs cv_label Computer Vision audio_label Audio multimodal Multi-Modal

Hardware

  • Any recent-ish machine with a CPU
  • GPUs
  • APUs

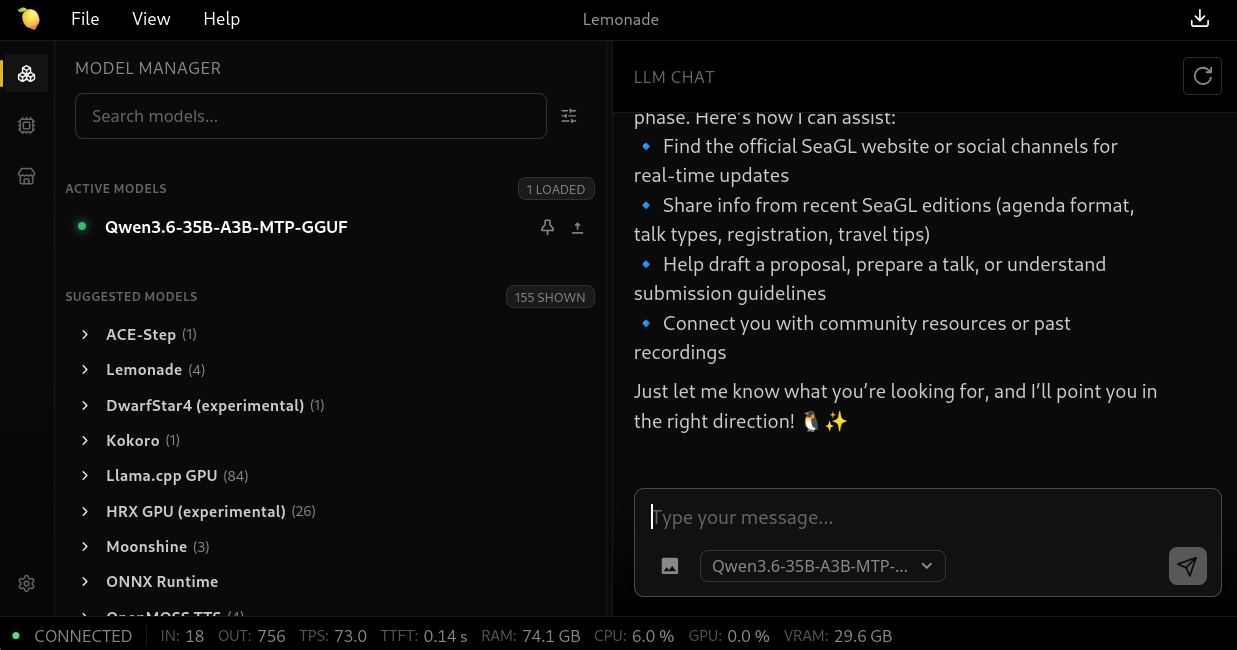
Lemonade Server

lemonade-server.ai

  • Local AI Toolbox
  • Servers
  • AI Models

Inference

Inference is the process of using a trained LLM to generate human-like text from a given input prompt.

per Huggingface

Inference Servers

Models

Size China United States
XS Qwen3.5 0.8B (~4GB) Gemma 4 E2B (~4GB)
S Qwen3.6 35B-A3B MTP (~24GB) Gemma 4 26B-A4B (~18GB)
M Qwen3.5 122B-A10B (~70GB) gpt-oss-120b (text-only) (~66GB)

Note

  • Estimates from unsloth.ai, for 4-bit quantization
  • CPU: choose XS; GPU: choose XS or S; APU: prefer M if it fits
  • All of these do vision, except for gpt-oss-120b
  • Checkout Mistral models from France

(V)RAM

ModelMemoryStack weights Model weights (static: parameters) activations Activations (tunable: context limit, slots) kv_cache KV cache (tunable: context limit, slots) prompt Prompt cache (tunable: cache slots)

(V)RAM Estimation

Formula Example
Model parameters * 0.5 bytes 35B * 0.5 = 17.5GiB
KV cache 32KiB * context size * slots 32KiB * 128K * 1 = 4GiB
Prompt cache KV-cache slot size * cache size 4G * 2 = 8GiB
Engine overhead 2-4GiB 2GiB

Total: ~32GiB

Note

Cache-size per token varies wildly. This is “napkin math” (inaccurate). Deploying the model is the best way to find out.

Local Observability

Install, Configure, Invoke

# lemonade
export LEMONADE_RPM=lemonade-server-2026.42.1-fc44.x86_64.rpm
wget https://github.com/lemonade-sdk/lemonade/releases/download/v2026.42.1/$LEMONADE_RPM
sudo dnf install -y ./$LEMONADE_RPM
sudo systemctl enable --now lemond

# local mlflow, telemetry stays on your machine
uvx mlflow server
# download a model
lemonade pull Gemma-4-E2B-it-GGUF

# connect lemonade to mlflow
lemonade config set telemetry.enabled=true \
  telemetry.otlp.endpoint=http://localhost:5000/v1/traces \
  telemetry.otlp.protocol=http/protobuf \
  telemetry.otlp.semantics='["otel_genai"]' \
  telemetry.otlp.headers='{"x-mlflow-experiment-id":"0"}'

# chat with a model
curl http://localhost:13305/v1/chat/completions -H "Content-Type: application/json" -d '{
  "model": "Gemma-4-E2B-it-GGUF",
  "messages": [{"role": "user", "content": "Repeat after me: 1"}],
  "temperature": 0.7
}'

Tip

Another approach that works well with MLflow is to route traffic through its AI gateway feature.

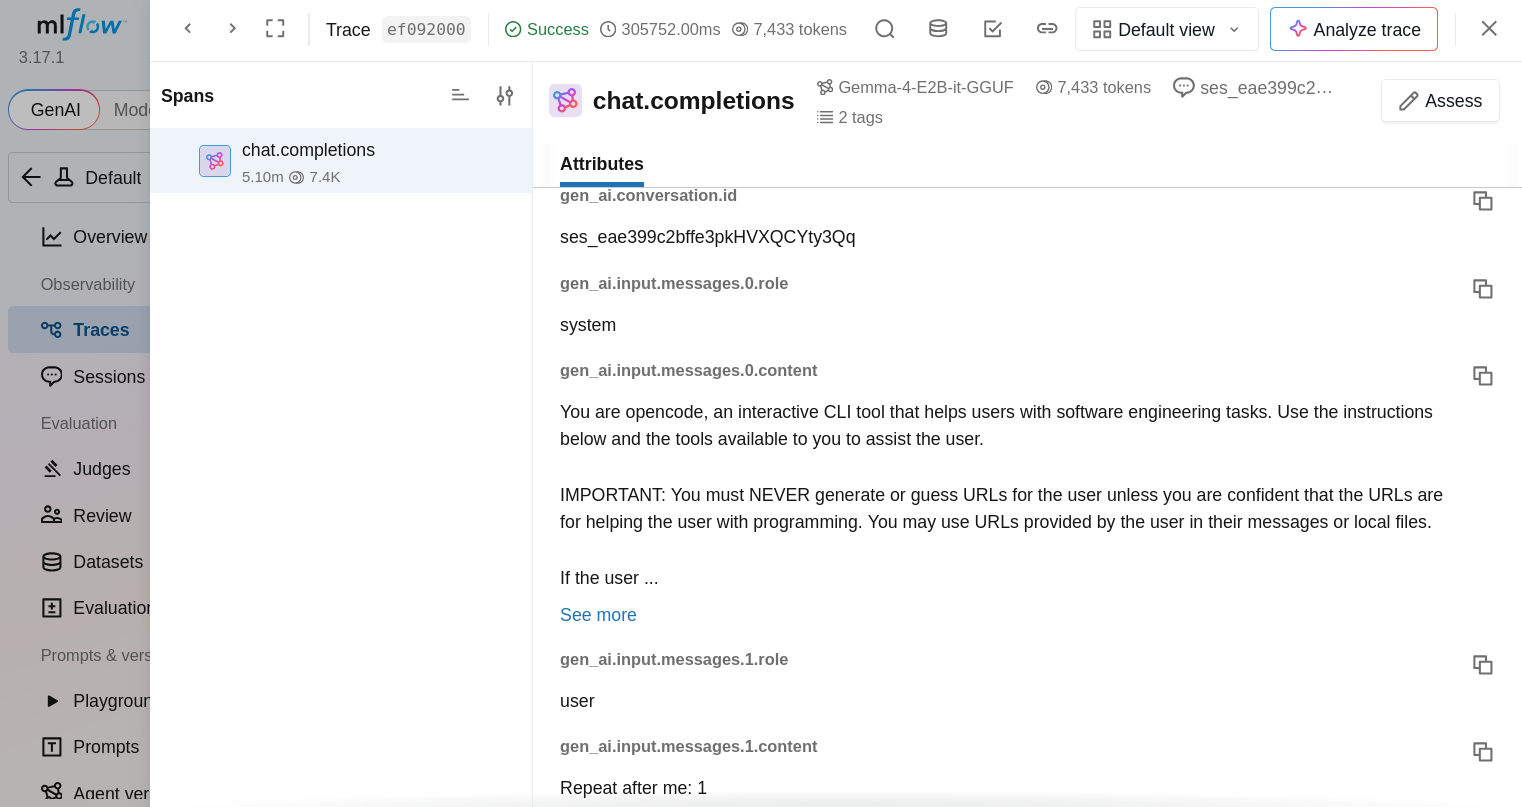
Example Trace

Agent Frameworks

Apply LLMs to do something useful; aka. harnesses

Chat UIs

Warning

Open WebUI’s license is not an OSI-approved “open source” license, because of an additional “branding protection clause”.

Coding Agents

Chat Assistants

Warning

Dangerous! Inherent security risks. Sandboxing is a must.

Sandboxing

OpenShell - Local Inference Setup

openshell provider create \
    --type openai \
    --name lemonade \
    --credential OPENAI_API_KEY='none' \
    --config OPENAI_BASE_URL=http://localhost:13305/v1
openshell inference set \
    --provider lemonade \
    --model Qwen3.6-35B-A3B-MTP-GGUF \
    --timeout 3600

Note

https://inference.local in any sandbox now routes to Qwen3.6 35B-A3B MTP running via lemonade.

OpenShell - OpenCode Config

export OPENCODE_CONFIG_CONTENT='{
  "$schema": "https://opencode.ai/config.json",
  "model": "local/local",
  "provider": {
    "local": {
      "npm": "@ai-sdk/openai-compatible",
      "options": {
        "baseURL": "https://inference.local/v1",
        "apiKey": "none"
      },
      "models": {
        "local": {
          "name": "local",
          "modelID": "local"
        }
      }
    }
  }
}'

OpenShell - OpenCode Sandbox

openshell sandbox create \
    --provider lemonade -- \
    bash -c \
    "OPENCODE_CONFIG_CONTENT='$OPENCODE_CONFIG_CONTENT' opencode"

Agent Stack

AgentStack harness Harness/Framework (e.g. opencode) environment Environment/Sandbox (e.g. openshell) inference Inference (e.g. llama.cpp)

Image Generation

Diffusion models construct a “new” image by refining noise into something recognizable by humans and the model, according to a prompt.

Image Generation - Servers

Resources

Q&A

Thanks for coming to my talk!

@kahowell@mastodon.social

https://kahowell.net